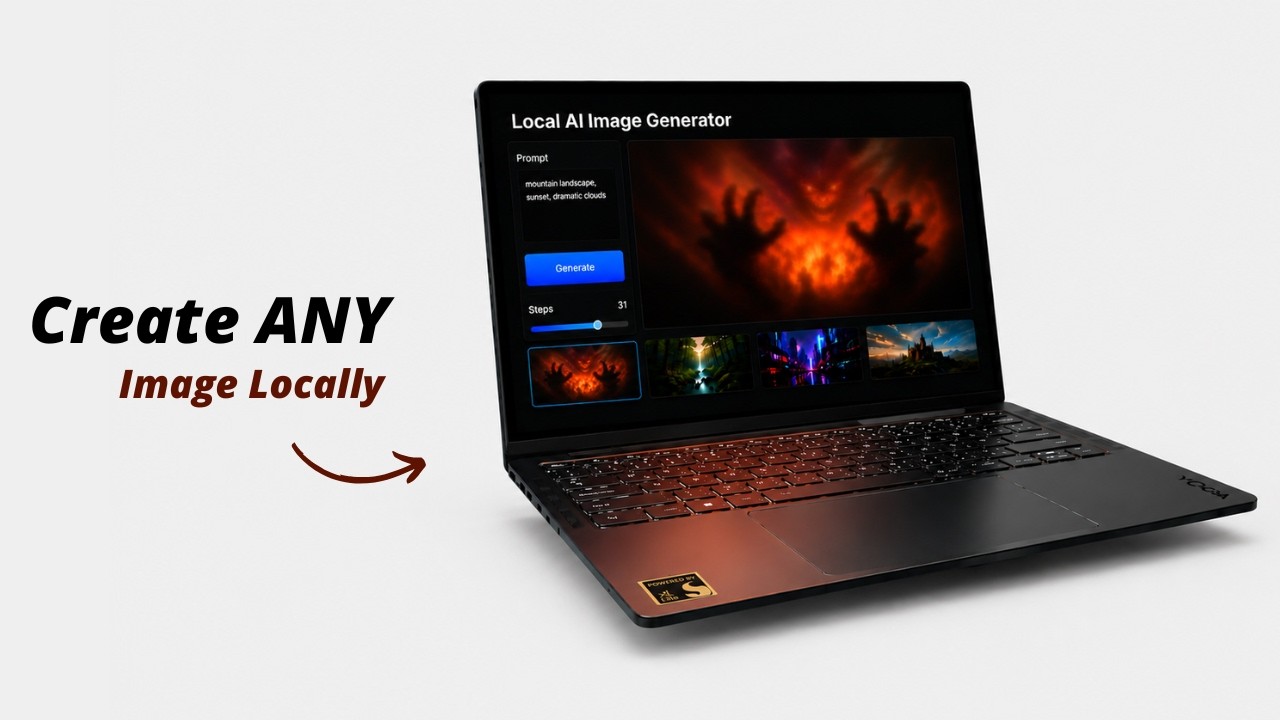

diff --git a/.gitattributes b/.gitattributes
new file mode 100644
index 0000000..dfdb8b7
--- /dev/null
+++ b/.gitattributes
@@ -0,0 +1 @@
+*.sh text eol=lf
diff --git a/.gitignore b/.gitignore
index 35a19d6..7cb43f3 100644
--- a/.gitignore
+++ b/.gitignore
@@ -1,27 +1,48 @@
-# Ignore large Stable Diffusion model weights (exceeds GitHub file limits)
-app/models/*.safetensors
-app/models/*.gguf
-app/models/*.ckpt
-app/models
-app/outputs/
+# Downloaded AI models
+app/models/
+app/openvino-models/
+app/llm-models/
+app/speech-models/
+app/tts-models/
-# Ignore portable Node.js binaries and packages
-app/tools/
-**/node_modules/
-node_modules/
-
-# Ignore backend folder completely (contains massive DLLs, EXEs, and ZIPs >1GB)
+# Downloaded portable runtimes/backends
app/backend/
+app/llm-backend/
+app/speech-backend/
+app/tts-runtime/
+app/tools/
-# Ignore local IDE and OS temp files
+# Generated files
+app/config/
+app/cache/
+app/dist/
+app/outputs/
+app/transcriptions/
+app/tts-outputs/
+app/tts-cache/
+
+# Dependencies and platform-specific copies
+**/node_modules/
+**/node_modules_*/
+**/node_modules_windows/
+**/node_modules_linux/
+**/node_modules_mac/
+**/.active_modules_os
+
+# Partial downloads and archives
+*.part
+*.tmp
+app/tools/*.zip
+app/tools/*.tar.gz
+app/tools/*.tar.xz
+
+# Logs and caches
+*.log
+__pycache__/
+*.pyc
+
+# OS/editor files
.vscode/
.idea/
.DS_Store
Thumbs.db
-*.log
-*.tmp
-
-
-
-# output images folder
-/app/outputs
\ No newline at end of file
diff --git a/README.md b/README.md
index f02ba37..3638f91 100644
--- a/README.md
+++ b/README.md
@@ -1,68 +1,146 @@
-# πΌοΈ Local AI Image Generator
+# πΌοΈ Uncensored AI Studio
-### An easy, zero-setup Stable Diffusion GUI for Windows. Run GGUF & Safetensors models offline without Python configuration.
+
+ A premium, zero-configuration local AI studio and offline GUI for Stable Diffusion (Image Generation), LLMs (Chat), Whisper (Speech-to-Text), and Kokoro (Text-to-Speech). Powered by hardware-accelerated GPU and NPU execution on Windows, Linux, and macOS.
+
+
---
-## π Overview
-**Local AI Image Generator** is a zero-configuration, portable desktop environment for running Stable Diffusion (Safetensors/GGUF/CKPT) offline on Windows. Double-clicking `start.bat` automatically handles dependency setup, GPU backend matching (CUDA/Vulkan), and launches a high-performance local web workspace.
+
+## π Table of Contents
+* [What is Uncensored AI Studio?](#what-is-uncensored-ai-studio)
+* [Key Features](#key-features)
+* [Workspace & Engine Architecture](#workspace-architecture)
+* [Folder Architecture](#folder-architecture)
+* [Getting Started](#getting-started)
+ * [Windows Setup](#windows-setup)
+ * [Linux Setup](#linux-setup)
+ * [macOS Setup](#macos-setup)
+* [Hardware Compatibility & Acceleration](#hardware-compatibility-acceleration)
+* [Troubleshooting & FAQ](#troubleshooting-faq)
+* [Building From Source](#building-from-source)
+* [Licensing](#licensing)
---
-## β‘ Quick Start
-1. **Launch:** Double-click **`start.bat`** (downloads portable Node.js and pre-compiled GPU backend binaries on first run).
-2. **Add Models:** Drop `.safetensors`, `.gguf`, or `.ckpt` weights into `app/models/` (or download them via the **Model Manager** tab in the UI).
-3. **Generate:** Open `http://localhost:1420` in your browser, select your model, and write a prompt.
+## π What is Uncensored AI Studio?
+
+**Uncensored AI Studio** is a completely offline, zero-setup, self-contained AI studio for Windows, Linux, and macOS. Unlike cloud-based AI systems, it runs entirely on your own hardware with no censorship, tracking, subscriptions, or login requirements.
+
+It unifies four major local AI capabilities into one high-performance desktop interface:
+1. **π¨ Image Generation (Stable Diffusion):** Generate and edit high-quality images offline using `.safetensors`, `.gguf`, or `.ckpt` model weights.
+2. **π¬ Text Chat (LLMs):** Converse privately with open-source language models (GGUF format) powered by official, high-performance `llama.cpp` backends.
+3. **ποΈ Speech-to-Text (Whisper):** Transcribe voice recordings and speech to text in real-time with an integrated `whisper.cpp` engine.
+4. **π£οΈ Text-to-Speech (Kokoro TTS):** Convert text outputs into highly natural, lifelike vocal audio offline using the `Kokoro-82M` ONNX model.
---
-## β¨ Features
-* **100% Offline & Private:** Inference runs completely locally on your hardware.
-* **Auto-Detected GPU Acceleration:** Configures **CUDA** for Nvidia cards, and **Vulkan** for AMD or Intel Arc GPUs.
-* **Zero System Footprint:** Node.js is sandboxed inside the folder. No global environment paths are altered.
-* **Integrated Model Manager:** Paste a Hugging Face URL to download weights directly, or drag-and-drop local weight files to import them.
-* **Real-time Telemetry:** Monitor RAM, VRAM, CPU, and GPU load directly in the UI.
-* **Local Gallery:** Saves generated PNGs alongside prompt metadata JSONs to `app/outputs/`.
+## π Key Features
+
+* **100% Offline & Private:** Run inferences locally. No internet, telemetry, cloud logging, or API keys required.
+* **Zero-Install Portability:** Entire runtime (Node.js, models, GPU backends) is self-contained. Zero global system environment changes.
+* **Auto-Configured Acceleration:** Auto-detects hardware specs to load CUDA (Nvidia), ROCm (AMD), Vulkan (Intel/AMD/NVIDIA), Metal (macOS), or OpenVINO (Intel NPU) backends.
+* **Integrated Model Manager:** Paste Hugging Face URLs to download weights directly, or drag-and-drop local weights to import them.
+* **Live Performance Monitor:** Track CPU, RAM, GPU, and VRAM utilization in real-time directly inside the web UI.
+* **Local Output Gallery:** Saves generated images side-by-side with prompt parameters and metadata JSON files.
---
-## π Repository Structure
+## βοΈ Workspace & Engine Architecture
+
+To avoid exhausting system RAM or VRAM, text and image engines are mutually exclusive by default. You can switch between workspaces inside the UI:
+
+* **Image Generation Workspace:** Uses a dedicated `stable-diffusion.cpp` backend node. Model weights are stored in `app/models/`.
+* **Text Chat Workspace:** Uses a portable `llama.cpp` server backend. Model weights (.gguf) are stored in `app/llm-models/`. A small Qwen2.5 Coder starter model can be downloaded directly from the Text Chat panel.
+* **Speech Worker (Whisper):** Runs a localized `whisper-cli` process to convert your vocal input to text.
+* **Audio Output (Kokoro TTS):** Utilizes `kokoro-js` locally on the server side to read responses in natural voices.
+
+---
+
+## π Folder Architecture
+
```
-local-ai-image-generator/
-βββ start.bat # Main double-click entrypoint
-βββ LICENSE # MIT Open Source license
-βββ .gitignore
-βββ README.md
+Uncensored-AI-Studio/
+βββ windows.bat # Windows Launcher (Double-click entrypoint)
+βββ linux.sh # Linux Launcher (Terminal entrypoint)
+βββ mac.sh # macOS Launcher (Terminal entrypoint)
+βββ LICENSE # MIT Open Source License
+βββ .gitignore # Excludes models and output images from version control
+βββ README.md # Detailed system documentation
βββ scripts/
-β βββ setup.ps1 # Automated GPU-detect and environment installer
-β βββ reset.ps1 # Cleans runtime environments (keeps models & outputs)
-β βββ serve.cjs # UI web server and backend lifecycle manager
+β βββ setup/ # Platform setup and backend installers
+β βββ reset/ # Clean install & environment repair
+β βββ server/ # UI web server and backend lifecycle manager
+β βββ workers/ # Local worker processes
+β βββ build/ # Optional source build helpers
+β βββ config/ # Runtime configuration catalogs
βββ app/
βββ frontend/ # UI source code (Vite + React)
- βββ models/ # Place weights here (.safetensors, .gguf, .ckpt)
+ βββ models/ # Place image weights here (.safetensors, .gguf, .ckpt)
+ βββ llm-models/ # Place text GGUF weights here
βββ outputs/ # Saved images and parameters metadata
```
---
-## π₯οΈ GPU Compatibility Matrix
+## π Getting Started
+
+Ensure you have a modern web browser installed. Follow the quick guide below for your platform:
+
+### Windows Setup
+
+1. **Launch:** Double-click **`windows.bat`**.
+ > [!NOTE]
+ > On the first run, the script will automatically download a portable Node.js runtime and configure pre-compiled GPU/CPU backend binaries.
+2. **Add Models:** Drop `.safetensors`, `.gguf`, or `.ckpt` weights into `app/models/` (or download them via the **Model Manager** tab in the UI).
+3. **Generate:** Open `http://localhost:1420` in your browser, select your model, and write a prompt.
+
+### Linux Setup
+
+1. **Make executable:** Open a terminal in the project folder and make the script executable:
+ ```bash
+ chmod +x linux.sh
+ ```
+2. **Launch:** Run **`./linux.sh`**.
+ - **NVIDIA GPU Users:** You will be prompted to set up the high-performance **CUDA** backend (downloads prebuilt or automatically compiles from source as a fallback).
+ - **AMD Radeon Performance:** Run with **`./linux.sh --max-perf`** to add the ROCm backend (~1.3 GB download).
+ - **Intel Core Ultra NPU:** Run with **`./linux.sh --setup-openvino`** to configure Intel NPU support (requires Intel Linux NPU driver).
+3. **Add Models:** Drop your weights into `app/models/` or download them via the **Model Manager** tab.
+4. **Generate:** Open `http://localhost:1420` in your browser.
+
+### macOS Setup
+
+1. **Make executable:** Open a terminal in the project folder and make the script executable:
+ ```bash
+ chmod +x mac.sh
+ ```
+2. **Launch:** Run **`./mac.sh`**.
+ > [!IMPORTANT]
+ > The prebuilt macOS backend is optimized for **Apple Silicon (M1 or newer)** and uses **Metal** GPU acceleration. *(macOS Intel hardware is completely unsupported)*.
+3. **Add Models:** Drop your weights into `app/models/` or download them via the **Model Manager** tab.
+4. **Generate:** Open `http://localhost:1420` in your browser.
+
+---
+
+## π₯οΈ Hardware Compatibility & Acceleration
+
+### Windows
| GPU Vendor | Tech | Status | Notes |
| :--- | :--- | :--- | :--- |
@@ -71,24 +149,120 @@ local-ai-image-generator/
| **Intel Arc** | Vulkan | β Native | Maps `sd-vulkan.exe` for Intel hardware. |
| **Integrated / None** | CPU | β οΈ Fallback | Runs on logical CPU threads (slow). |
----
+### Linux
-## β±οΈ Performance Benchmarks
+| GPU Vendor | Primary | Fallback | Notes |
+| :--- | :--- | :--- | :--- |
+| **NVIDIA** | CUDA / Vulkan | Vulkan / CPU | Auto-detects NVIDIA. Prompt-driven CUDA setup downloads prebuilt or compiles from source. Falls back to Vulkan for GTX. |
+| **AMD Radeon** | ROCm | Vulkan | ROCm provides best AMD performance when host ROCm drivers are available. |
+| **Intel Arc / integrated** | Vulkan | CPU | Cross-vendor Vulkan support. |
+| **Intel Core Ultra NPU** | OpenVINO NPU | CPU | Requires the Intel Linux NPU driver, kernel 6.6+, Python 3, and `./linux.sh --setup-openvino`. |
+| **Integrated / None** | CPU | β | Runs on logical CPU threads (slow). |
-Typical generation times for an image with **20 steps** (e.g. 512x512 resolution; actual times can vary depending on specific hardware specifications, clock speeds, and system load):
+### macOS
-* **CUDA GPU (Nvidia RTX):** ~10 seconds.
-* **Vulkan GPU (AMD / Intel Arc):** ~89 seconds.
-* **GTX Vulkan Fallback (Nvidia GTX):** ~30 seconds (Vulkan runs significantly faster on legacy GTX series cards since they lack Tensor Cores).
-* **CPU (Fallback):** ~150 - 300+ seconds (highly dependent on processor core count, speed, and AVX instruction sets).
+| Hardware | Primary | Fallback | Notes |
+| :--- | :--- | :--- | :--- |
+| **Apple Silicon (M1 or newer)** | Metal | CPU | Uses the official Darwin arm64 stable-diffusion.cpp backend. |
+
+> [!IMPORTANT]
+> **System Requirements & Notes:**
+> - **64-bit Windows 10 or Windows 11** is required for the portable Node.js 22 runtime used by the Windows launcher.
+> - **glibc 2.38 or newer** is required for the prebuilt Linux backends (Ubuntu 24.04, Fedora 40+, etc.). The setup script will warn you if your glibc is older.
+> - **Linux OpenVINO NPU:** Intel Core Ultra, x86_64 Linux, kernel 6.6+, a working `/dev/accel/accel0` device, Python 3 with `venv`, and the Intel Linux NPU driver are required.
---
-## π οΈ Troubleshooting
-* **Reset Environment:** If a build fails or you want to clear dependencies, run `scripts/reset.ps1`. (This preserves your models and generated images).
-* **Port Conflicts:** The frontend uses `1420` by default. The backend tries `8080` first, then automatically falls back to a free port if `8080` is already busy.
+## π οΈ Troubleshooting & FAQ
+
+
+ Reset Environment: If a build fails or you want to clear dependencies
+
Run scripts/reset/reset.ps1 (Windows) or scripts/reset/reset.sh (Linux/macOS). This will clear temporary compilation and package caches to repair your environment. (Note: This preserves your model weights and generated output images).
+
+
+
+ Linux backends fail to start with GLIBC_2.38 not found
+
The prebuilt binaries require glibc 2.38+ (e.g. Ubuntu 24.04). If your distribution uses an older glibc version, you can upgrade your operating system or compile the backend from source (see the Building From Source guide below).
+
+
+
+ Port Conflicts: Default port address already busy
+
The web user interface runs on port 1420 by default. The GPU backend manager attempts to bind to port 8080 first, then automatically detects and falls back to a free system port if 8080 is already occupied.
+
+
+
+ Linux ROCm not loading for AMD Radeon GPUs
+
Ensure your AMD GPU hardware and host kernel are fully compatible with ROCm 7.13. If ROCm fails to initialize correctly, the application will automatically fall back to Vulkan acceleration.
+
+
+
+ Windows exits with code 3221225781 (0xC0000135)
+
This code means Windows could not locate a required backend DLL:
+
+
For AMD/Intel Vulkan: Update your GPU driver to one with full Vulkan runtime support, then rerun the setup script to restore app/backend/win/vulkan/.
+
For NVIDIA CUDA: Install or update your NVIDIA graphics driver, then rerun the setup script to restore the CUDA runtime DLLs.
+
+
+
+
+ Generation shows "server is not responding or crashed"
+
This indicates that the local backend engine process terminated. Check your launch terminal (where you executed windows.bat, ./linux.sh, or ./mac.sh) for the exact console error. Common causes include glibc version mismatches, missing Vulkan drivers, or system out-of-memory (OOM) issues.
- Configure size, quality, and performance controls for image generation.
-
-
-
-
- {/* Left Column: Size & Quality */}
-
- {/* Card 1: Picture Size & Shape */}
-
-
-
- 1. Picture Size & Shape
-
-
- {isSD15OrCustom && (
-
-
-
- Low-VRAM Protection Active: Capped at 512x512 for the loaded SD 1.x model ({activeModel}). Generating at larger sizes (like 1024x1024) is disabled to prevent out-of-memory crashes on your {specs && specs.gpu_name && !specs.gpu_name.includes("Loading") ? specs.gpu_name : "graphics processor"}.
-
-
- {isSD15OrCustom
- ? "*Standard Speed Mode (512px) is forced for SD 1.5 / custom models to ensure stable local generations."
- : "*Use High Quality (1024px) for Flux or SDXL models. Use Standard (512px) for SD 1.5."}
-
-
- updateConstraint("steps", parseInt(e.target.value))}
- min="1"
- max="60"
- />
-
- The number of times the AI cleans up the image. More steps = sharper details, but takes longer.
-
-
-
- {/* Random Seed DNA */}
-
-
-
- updateConstraint("seed", parseInt(e.target.value) || -1)}
- placeholder="-1 for a brand new image..."
- style={{ flex: 1, height: "40px" }}
- />
-
-
-
-
-
-
-
- {/* Right Column: Speed & System */}
-
- {/* Card 3: Performance hacks */}
-
-
-
- 3. System Settings
-
-
-
-
-
-
- {availableBackends.map((backend) => (
-
handleBackendChange(backend.id)}
- title={backend.id === "cuda" ? "CUDA appears only when an NVIDIA CUDA backend is available." : undefined}
- >
- {backend.label}
-
- ))}
-
-
- CPU is slow but safest. Vulkan works on supported GPUs. CUDA is shown only when NVIDIA CUDA support is available.
-
- {constraints.backendType === "cuda" && specs?.gpu_name && String(specs.gpu_name).toLowerCase().includes("gtx") && (
-
- Performance Alert: Your graphics card ({specs.gpu_name}) is a GTX-series GPU which lacks hardware Tensor Cores. Running in CUDA mode will be up to 3x slower. We strongly recommend switching to Vulkan GPU for optimal generation speed.
-
+ β οΈ Note: The first time loading this model, compilation on the Apple Neural Engine (NPU) can take 3β4 minutes. Subsequent loads will be almost instant.
+
- No models detected in app/models/. Download from the library below or import a file.
+ {activeModelType === "image"
+ ? "No image models detected in app/models/. Download from the library below or import a file."
+ : activeModelType === "text"
+ ? "No text models detected in app/llm-models/. Download from the library below or import a file."
+ : activeModelType === "speech"
+ ? "No speech models detected in app/speech-models/. Download from the library below or import a .bin file."
+ : "No TTS models detected in app/tts-models/. Install Kokoro from the library below or import a .json manifest."}
- Download any GGUF or Safetensors model from Hugging Face or other sites directly to your models folder.
+ Download any {activeModelType === "image" ? "Safetensors" : activeModelType === "text" ? "GGUF" : activeModelType === "speech" ? "Whisper .bin" : "Kokoro manifest"} model from Hugging Face directly to your models folder.
{isUrlDownloading ? (
@@ -825,18 +1890,18 @@ function ModelManager({ activeModel, setActiveModel, serverRunning, setServerRun
-
Unload Current Model?
+
Model Already Active
- "{activeModel}" is already loaded. Unload it before loading "{pendingLoadModel}".
+ "{pendingLoadModel.activeRuntime?.model}" is already loaded as a {pendingLoadModel.activeRuntime?.label || "model"} model. Unload it before loading "{pendingLoadModel.modelId}" as a {getModelTypeLabel(pendingLoadModel.targetType)} model.
+ The model {vramWarning.modelId} is approximately {vramWarning.modelSizeGb.toFixed(1)} GB, which exceeds your currently available GPU VRAM of {vramWarning.freeVramGb.toFixed(1)} GB free (out of {vramWarning.totalVramGb.toFixed(1)} GB total).
+
+ Loading this model on your GPU may fail, crash the backend, or cause extremely slow generation due to memory spilling.
+
+
+
+
+ Auto uses a GPU whisper.cpp backend when its binary exists, then falls back to CPU.
+
+
+
+
+
+
+
+ Default language for transcribing audio. (Recommended: Auto detect)
+
+
+
+
+
+ CPU Threads
+ {speechSettings.threads || 4}
+
+ updateSpeechSetting("threads", parseInt(e.target.value))}
+ min="1"
+ max={specs?.cpu_cores_logical || 16}
+ style={getSliderStyle(speechSettings.threads || 4, 1, specs?.cpu_cores_logical || 16)}
+ />
+
+ Number of threads to allocate for transcription. (Recommended: 4)
+
+
+
+
+
+
+ {/* Right Column */}
+
+ {/* Translation options */}
+
+
+
+ Translation Settings
+
+
+ updateSpeechSetting("translate", val)}
+ label="Translate to English"
+ description="Auto-translate foreign languages to English during transcription"
+ />
+
+
+ {/* Preview circles for primary and secondary colors */}
+
+
+
+
+
+ {t.type}
+
+
+
+ );
+ })}
+
+
+ {/* Divider separating sub-sections inside the single card */}
+
+
+ {/* Text & Interface Size Sub-section */}
+
+
+ Text & Interface Size
+
+
+
+ Font Size
+ {fontSize || 16}px
+
+ setFontSize(parseInt(e.target.value))}
+ min="12"
+ max="24"
+ step="1"
+ style={getSliderStyle(fontSize || 16, 12, 24)}
+ />
+
+ Adjusts the global font size of the application text, including chat replies and settings labels. Default is 16px.
+
+
+
+
+ )}
+ >
+ );
+
+ return (
+
+ {/* Page Header */}
+
+
Settings & Parameters
+
+ Configure your AI models for optimal performance.
+
+ Initializing llama.cpp server and loading the model weights into memory. This can take up to 30 seconds depending on model size and hardware speed.
+
+
+
+ Cancel Load
+
+
+ ) : (
+ <>
+ {messages.length === 0 && (
+
+
+
+
+
Local AI Chat
+
Your private, offline AI assistant. Choose a GGUF model above and start a conversation β everything stays on your machine.
+ {status.ready && (
+
+ {[
+ { icon: "βοΈ", text: "Write a professional email to reschedule a meeting" },
+ { icon: "π‘", text: "Explain how transformers work in simple terms" },
+ { icon: "π", text: "Help me debug this Python code" },
+ { icon: "π", text: "Summarize the key points of a topic" },
+ ].map((s, i) => (
+ { setInput(s.text); }}
+ >
+ {s.icon}
+ {s.text}
+
+ ))}
+